Documentation menu
Time to restore (MTTR)
What it is
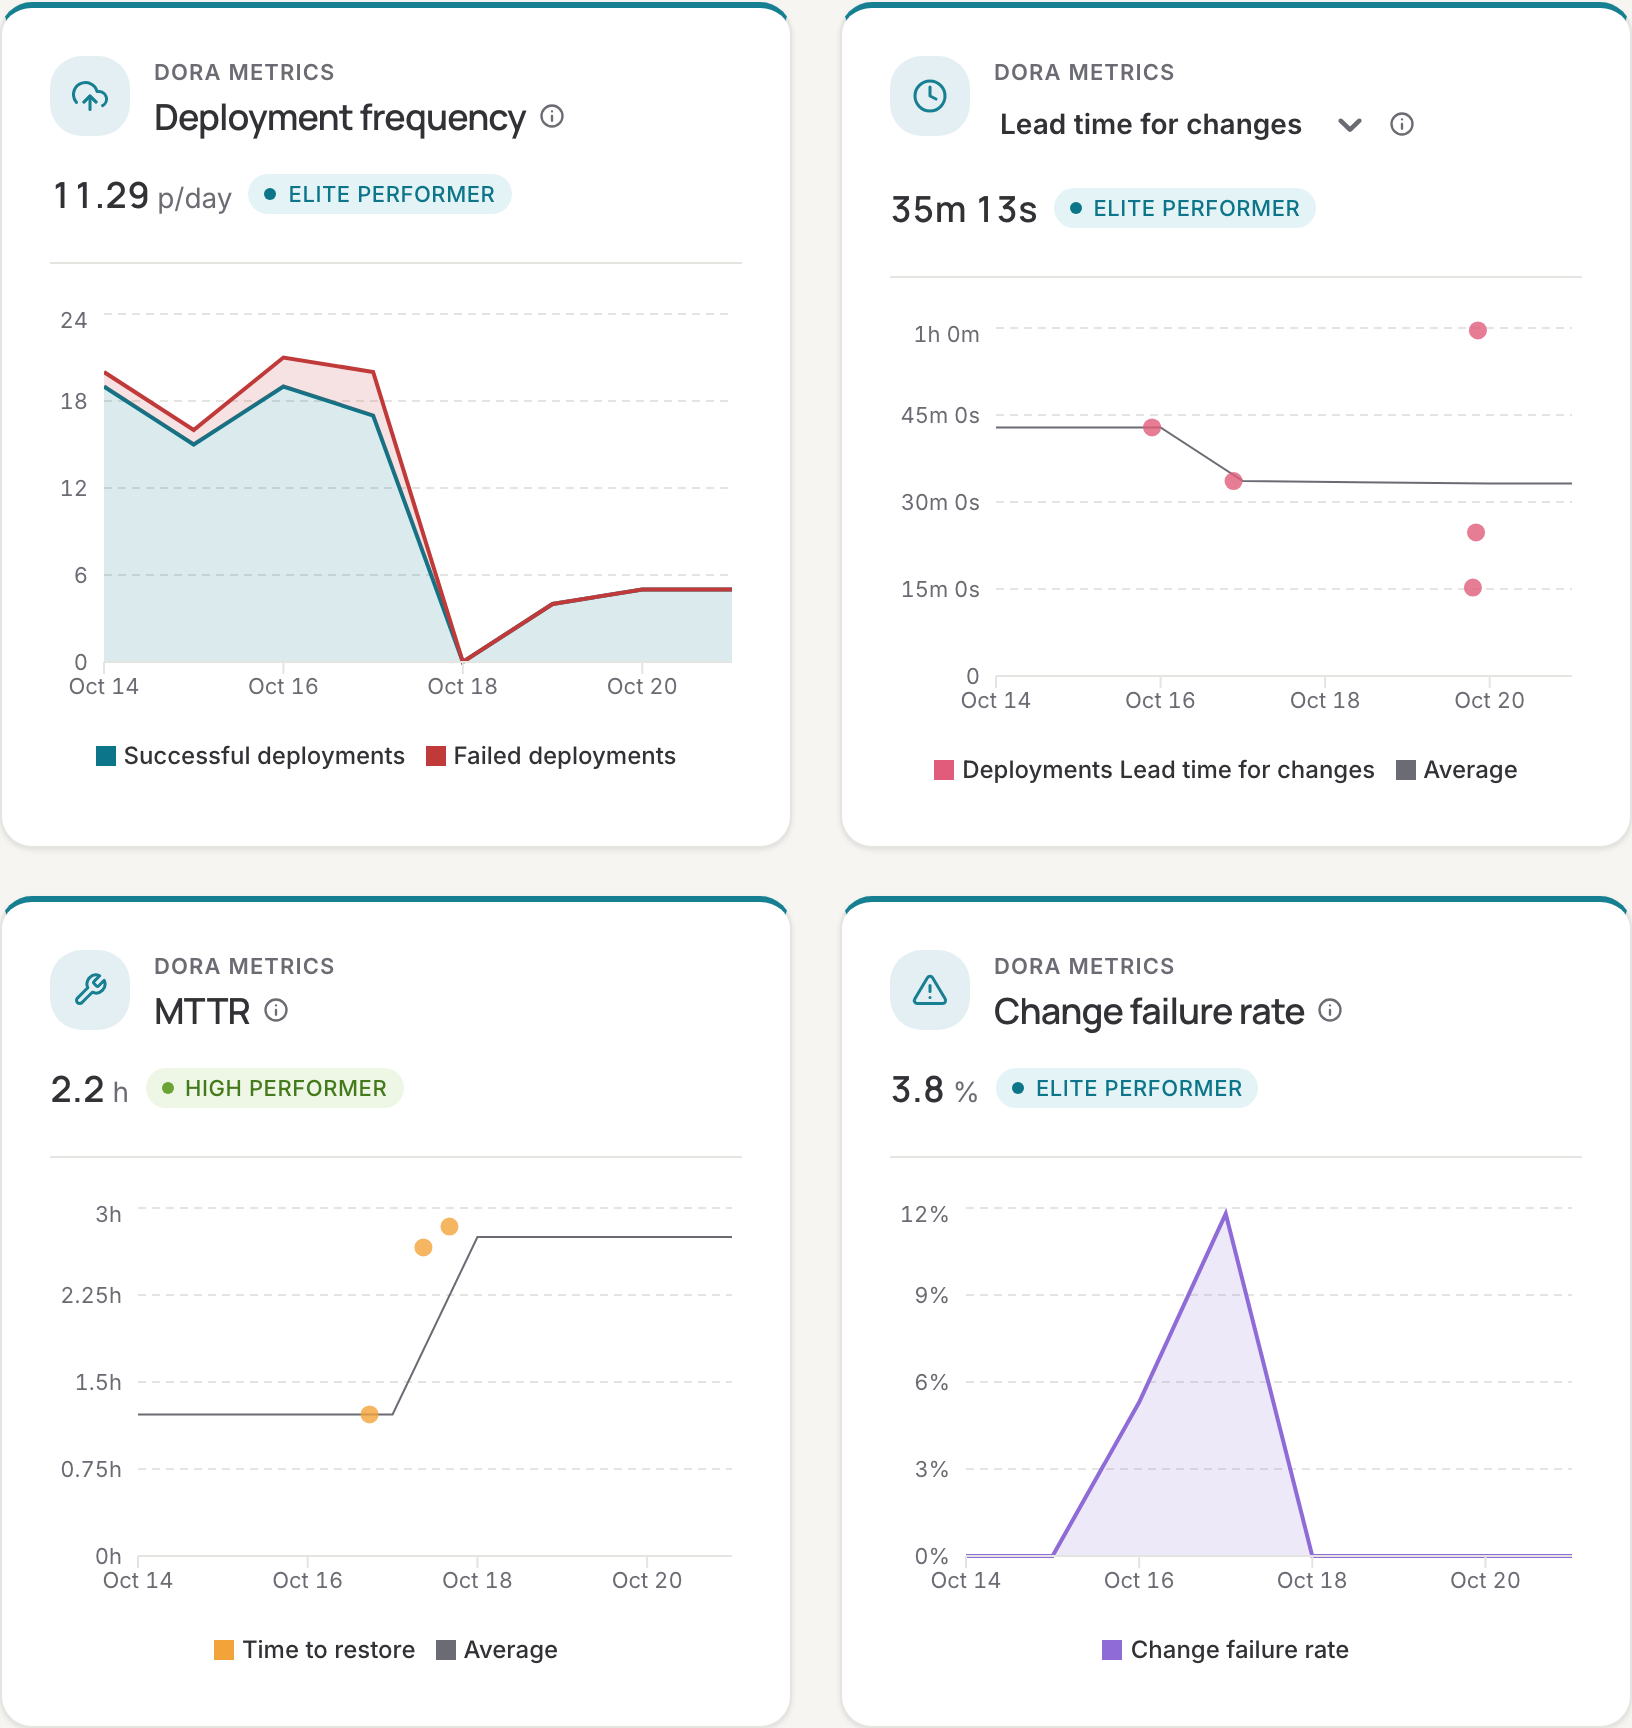
Time to restore, also called mean time to recovery (MTTR), is one of the four DORA metrics. It measures how long it takes to recover from a failure in production: from the moment the system fails until it is fully working again.
Reading it
Outages hit customers directly, so time to restore should be as short as possible. It depends on how fast a problem is detected (alerting), how fast the cause is found, and how fast a fix can be shipped, which is where deployment frequency and lead time come back in: a team that deploys several times a day restores in minutes, a team that releases monthly waits for the next window. The metric alone does not say which part took the time; the error budgets and the pipeline data do.
Performance tiers
| Tier | Time to restore |
|---|---|
| Elite | Less than one hour |
| High | Less than one day |
| Medium | Less than one week |
| Low | Between one week and one month |
In Agile Analytics
Time to restore is estimated from hotfix and revert merge requests: from the production deployment that was live when the fix was opened until the fix reached production. SLO alerts mark a deployment as failed (see change failure rate) but do not set the recovery time, because an alert's length is its measuring window, not the outage. Teams without hotfix or revert merge requests in the period see no value.